Chapter 6 · Quantitative Finance
Portfolio Allocation: The Math Behind the Efficient Frontier
Derive Markowitz mean-variance optimization and build the efficient frontier from scratch in Python, then see why the optimal portfolio is fragile.
By Nathan Updated 11 min Intermediate

On this page
In Chapter 5 we took a single stock apart and found that its returns are roughly normal but fatter in the tails than the bell curve admits. The obvious next question is what happens when you hold more than one thing at once. We first met that idea all the way back in Chapter 1, where splitting a bet into many uncorrelated pieces kept the expected value fixed while collapsing the risk of ruin. That was diversification in its simplest form. This chapter is where we give it a proper mathematical treatment.
By now we have a whole menu to choose from. We can hold stocks, government bonds, corporate bonds, and options, and we can buy them across markets in Japan, Germany, the United Kingdom, the United States, and Canada. Faced with all of that, a sensible investor is not going to bet everything on one name, they are going to spread their capital around. The question this post answers is how to spread it well rather than arbitrarily. The model we use is the one Markowitz developed and Sharpe refined, the work that founded modern portfolio theory and won a Nobel Prize, and its central object is the efficient frontier.
Foundations of Portfolio Allocation
Before we get into the mechanics, we need to agree on the rules of the game. The model rests on a handful of simplifying assumptions, and their only job is to make the problem tractable enough to solve in closed form.
Core assumptions
We work with a single-period decision. You invest all of your capital at and cash out entirely at time , with no trading in between. Inside that world we assume:
- assets. The investable universe is assets, which might be the whole market or some subset left after screening for things like liquidity or ethical criteria.
- Joint normality. The simple returns of those assets are jointly normally distributed, so their expected returns live in an column and their risk lives in an variance-covariance matrix .
- Frictionless trading. An investor with wealth can buy any asset without restriction and without moving the market price.
- Unrestricted short selling. Investors can short any asset and use the proceeds to fund other positions.
We lean on the single-period model purely for its simplicity. It does ignore the fact that real investors rebalance as new information arrives, but in exchange it spares us the headache of transaction costs and path dependence, and it still gives a clean baseline for understanding diversification.
Simple returns
When we price derivatives later, we will prefer log returns because they behave better over long horizons. For building portfolios, though, simple returns are the right tool, because they are additive across assets. Say you put euros into a stock with annualised simple return . Over a horizon :
- Value at is .
- Value at is .
Split the wealth across two assets, putting into one and into the other, and the total portfolio value at is:
Defining the weights as and , the portfolio return collapses into a clean linear combination:
Try the same thing with log returns and the algebra turns ugly fast. The portfolio value becomes:
and solving for the portfolio return gives:
That relationship is nonlinear and genuinely painful to optimise. Unless is small enough that we can lean on the approximation , log returns make portfolio aggregation a mess, which is exactly why simple returns win here.
The normality assumption is doing a lot of work in the background. We keep it mainly for tractability, and it is worth flagging now that the fat tails we found in Chapter 5 are precisely where it starts to fail. Its payoff is that it lets us describe a portfolio’s entire return profile with just two numbers: the mean and the variance.
Building the Risk and Return Model
With the assumptions in place, we can turn the words into algebra. To optimise a portfolio we need to define our variables and write down the model that trades the appetite for return against the reality of risk.
Our control variable is the allocation vector, an column , where each element is the fraction of total wealth put into asset . Because these are fractions of a whole, the first constraint is simply that they add up to 1, meaning we deploy exactly 100% of the capital. Using a vector of ones, that is:
We could also insist that no short selling is allowed by requiring , but we will first solve the unconstrained version, because it reveals the market’s underlying geometry most clearly.
We obviously want a high expected return, which is just . Maximising return on its own is a trap, though, because the model would happily tell you to pour 100% of your money into the single most volatile, highest-growth stock available. To keep it honest we measure risk with the portfolio’s variance. For two stocks the variance depends not only on their individual volatilities and but also on how they move together, and for assets we capture all of those relationships in the variance-covariance matrix . That lets us write total portfolio risk as a quadratic form:
Solving Mean-Variance Optimisation with Lagrange Multipliers
The goal of mean-variance optimisation is to find the allocation that gives the least risk for a chosen target return . So we want to:
- Minimise
- Subject to (hit the target return) and (spend exactly the budget)
The standard way to solve a constrained optimisation like this is the method of Lagrange multipliers. We introduce one multiplier for each constraint, and , which turns the problem into an unconstrained one. Taking derivatives and solving the resulting linear system leads to a genuinely important discovery: the relationship between risk and return is not a straight line, it is a hyperbola. The variance of the optimal portfolio simplifies to:
That equation traces a hyperbola in risk-return space, and it is the famous efficient frontier. Every point on the curve is a portfolio that delivers the lowest possible risk for its level of return. The three constants , , and are summary statistics of the whole opportunity set, built entirely from the expected returns and the inverse covariance matrix of the assets you picked:
| Constant | Formula | What it does |
|---|---|---|
| The total precision of the asset set. It fixes the risk of the safest portfolio, since the minimum-variance risk is . | ||
| The link between the assets’ returns and their risk structure. The minimum-variance portfolio earns . | ||
| How much return the assets can reach given their risk, driving the steepness of the frontier. |
Building the Efficient Frontier in Python with NumPy
Now we can turn the matrix algebra into code. Using numpy for the linear algebra, we set up four hypothetical assets, compute the constants , , and , and then solve for the optimal allocation vector at a target return.
import numpy as np
import matplotlib.pyplot as plt

def optimize_portfolio(returns, cov_matrix, target_return):
    """
    Calculates the optimal weights using the Lagrange multiplier analytical solution.
    """
    # Prepare the inputs
    V = np.array(cov_matrix)
    V_inv = np.linalg.inv(V)
    mu = np.array(returns).reshape(-1, 1)
    ones = np.ones((len(returns), 1))
    R = target_return

    # Calculate the market constants (a, b, c)
    a = (ones.T @ V_inv @ ones).item()
    b = (mu.T @ V_inv @ ones).item()
    c = (mu.T @ V_inv @ mu).item()
    det = a * c - b**2

    # Solve for the Lagrange multipliers (lambda_1 and lambda_2)
    lambda_2 = (a * R - b) / det
    lambda_1 = (c - b * R) / det

    # Optimal weights: X = V^-1 (lambda_1 * 1 + lambda_2 * mu)
    weights = V_inv @ (lambda_1 * ones + lambda_2 * mu)

    return weights.flatten(), a, b, c

def plot_efficient_frontier(asset_returns, cov_matrix, a, b, c):
    """Plot the efficient frontier chart."""
    det = a * c - b**2
    r_min = b / a
    target_returns = np.linspace(r_min - 0.05, r_min + 0.1, 200)

    # Analytical variance: sigma^2 = (a R^2 - 2 b R + c) / (a c - b^2)
    variances = (a * target_returns**2 - 2 * b * target_returns + c) / det
    volatilities = np.sqrt(variances)

    plt.figure(figsize=(10, 6))
    plt.plot(volatilities, target_returns, color='blue', linestyle='--', label='Min-Var Frontier')

    # The efficient frontier is the upper branch (returns >= r_min)
    efficient_idx = target_returns >= r_min
    plt.plot(volatilities[efficient_idx], target_returns[efficient_idx],
             color='darkblue', linewidth=3, label='Efficient Frontier')

    # Mark the Global Minimum Variance Portfolio (GMVP)
    plt.scatter(np.sqrt(1 / a), r_min, color='red', label='GMVP', zorder=5)

    # Plot the individual assets
    plt.scatter(np.sqrt(np.diag(cov_matrix)), asset_returns, marker='X', color='black', label='Assets')

    plt.title('The Markowitz Efficient Frontier')
    plt.xlabel('Risk (Volatility)')
    plt.ylabel('Expected Return')
    plt.legend()
    plt.grid(True, linestyle=':', alpha=0.6)
    plt.savefig('efficient_frontier_plot.png')

# --- Example usage ---

# Four assets with expected annual returns
asset_returns = np.array([0.08, 0.12, 0.15, 0.10])

# A stylized covariance matrix
cov_data = [
    [0.005, 0.002, 0.001, 0.001],
    [0.002, 0.008, 0.003, 0.002],
    [0.001, 0.003, 0.012, 0.002],
    [0.001, 0.002, 0.002, 0.007],
]

target = 0.11  # we want an 11% return
weights, a, b, c = optimize_portfolio(asset_returns, cov_data, target)

print(f"Optimal Weights for {target*100}% Return:")
for i, w in enumerate(weights):
    print(f" Asset {i+1}: {w*100:.2f}%")

# Resulting portfolio volatility
portfolio_variance = (a * target**2 - 2 * b * target + c) / (a * c - b**2)
print(f"\nPortfolio Volatility (Std Dev): {np.sqrt(portfolio_variance)*100:.2f}%")

plot_efficient_frontier(asset_returns, cov_data, a, b, c)At an 11% target the optimiser spreads the money fairly evenly across the four assets and lands on a portfolio with a volatility of 5.67%, which is lower than any of the individual assets could manage on their own. That is the whole promise of diversification stated as a number. Reading a single set of weights off a script does not really convey what the frontier is, though, because the frontier is not a point. It is a whole curve, and the best way to understand it is to bend it yourself.
Why the Optimal Portfolio Is So Fragile
The widget below is that curve for three assets. Each slider sets one asset’s expected return, and there is a single correlation slider that controls how tightly the assets move together. Drag any of them and the entire hyperbola reshapes, the red minimum-variance point slides along it, and the green capital-market line pivots onto a new tangency portfolio. The last slider walks a target-return marker along the frontier and reads out the weights it implies underneath, negative ones included.
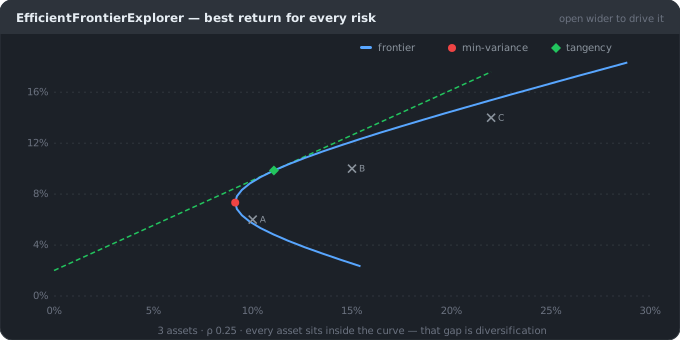
The dashed lower half of the hyperbola shows the portfolios with the least variance for each return, and the red point marks the global minimum-variance portfolio, the single lowest-risk mix you can build, sitting at . The individual assets all show up as crosses that fall strictly inside the curve, which is the entire argument for diversification in one picture: a well-chosen blend beats any single asset held alone. No rational investor would ever pick a portfolio on the lower branch, since it takes the same risk for less return, so the efficient frontier proper is only the upper half of the curve.
What the Efficient Frontier Does and Does Not Tell You
We took the loose idea of diversification from Chapter 1 and turned it into something exact: a frontier of portfolios that squeeze the most return out of every level of risk, derived cleanly from the expected returns and the covariance matrix. That is a real and useful piece of machinery, and it underlies how serious money actually gets allocated. It is also only as trustworthy as the estimates you feed it, which is a caveat worth carrying forward rather than filing away.
Notice too that we now have two of the three ingredients we will need to price an option: a model for how a stock’s returns are distributed, from Chapter 5, and a way to think about risk and the risk-free rate, from here and Chapter 4. The missing piece is what happens when a payoff depends on the stock in a nonlinear way, which is where options come in.
Next up is Chapter 7: Options, Calls, and Puts. We introduce the instruments whose value bends rather than moves in a straight line with the underlying, build up their payoff diagrams from scratch, and separate an option’s intrinsic value from its time value. It is the last conceptual piece we need before Chapter 8’s Value at Risk and, further out, the Black-Scholes pricer we derive in Chapter 11.
⚠️ Financial Education Disclaimer
The quantitative models and Python code provided in this post (including the Markowitz Mean-Variance Optimization) are for educational and research purposes only.
- Not Financial Advice: This content does not constitute professional financial or investment advice.
- Model Assumptions: The Markowitz model relies on historical data and the assumption of “Joint Normality,” which often fails during real-market “Black Swan” events. Past performance is not indicative of future results.
- Risk of Loss: Quantitative trading and portfolio allocation involve significant risk. You should consult with a certified financial advisor before making any investment decisions.
Get the next part
New parts of Finding P values and false hope land in your inbox the day they publish. No spam, unsubscribe in one click.
We send your address to Kit, our email provider, and ask you to confirm by email before anything is sent. See our Privacy Statement.